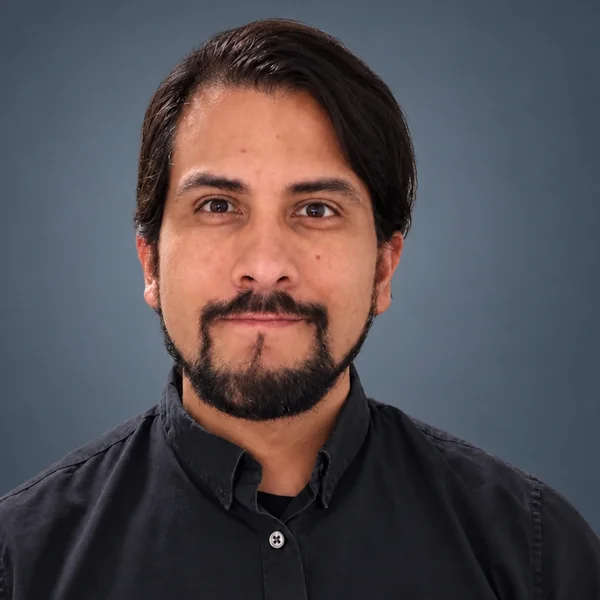
About me
Data engineer. I build pipelines that are tested, monitored and built to last.
I'm a data engineer with more than six years of experience designing and running data integration pipelines for companies in finance, insurance, mobility and marketing, as a consultant at Epsilon France (Publicis Groupe) and then as a data engineer at RiverBank and Corum L'Épargne.
I've worked in both worlds: distributed Big Data processing with Spark, Scala and Hadoop, and more traditional platforms built on SQL, Azure Data Factory, Apache NiFi and Google BigQuery. Across them, I focus on what keeps pipelines healthy in production: automated tests, monitoring, data quality and code that the next engineer can maintain.
Today I work on the modern lakehouse stack. I first worked with Data Vault on Corum's data platform; my latest project integrates six European company registers on Databricks and AWS with a medallion architecture, SCD Type 2 history and automated data-quality gates, and I earned the AWS Certified Cloud Practitioner certification in October 2026.
How I work
- Explicit over implicit. Declared schemas instead of inference, configuration instead of copy-paste, and failures that are loud instead of silent.
- Model for change. Sources change their formats and their data. I separate raw history from business rules so a change in one place doesn't break everything downstream.
- Cost-aware cloud. Serverless where it fits, and incremental work where it pays, like geocoding only the addresses that are new.
Experience
-
January 2023 – January 2024
Data Engineer · Corum L'Épargne
International real-estate investment company
- Built and maintained automated ETL pipelines in Azure Data Factory integrating financial and customer data, from linked services and transformations to orchestration.
- Wrote SQL queries, stored procedures and other database objects to optimise processing.
- Delivered on a data platform modelled with Data Vault.
-
September 2022 – December 2022
Data Engineer · RiverBank
- Worked on a framework to standardise how PySpark data flows are developed.
- Introduced automated unit tests with pytest to make delivery more reliable.
- Delivered within a microservices-based data platform.
-
October 2017 – August 2022
Big Data Consultant · Epsilon France (Publicis Groupe)
Data-marketing unit of Publicis Groupe
Delivered data automation projects (ingestion, transformation, orchestration, monitoring and incident correction) for clients in banking, insurance, retail and mobility, on private and public cloud platforms.
Client missions
-
Mobilize Financial Services · 2020 – 2022
Built and maintained multi-source ETL pipelines with Apache NiFi and Python, with traceability and data integrity, feeding data science and marketing teams. During the platform migration to Google BigQuery, rebuilt transformations in SQL and reconciled outputs so both platforms produced identical results.
-
PMU · 2020
Developed Apache Spark (Scala) pipelines on a Hadoop platform to load operational data into the data lake, added automated tests to improve data quality, and handled monitoring, corrections and orchestration.
-
Allianz France · 2017 – 2019
Modernised ETL processes and automated data workflows on a private cloud, turning Python notebooks into production-ready jobs in collaboration with the platform teams.
-
Certifications
Skills & tools
- Languages
- Big Data
- Cloud & lakehouse
- Data modelling
- Orchestration
- Quality & DevOps
Education
- Master's degree (M2), Data and Knowledge Université Paris-Saclay · Télécom ParisTech · 2016 – 2017
- Master's degree (M1), Software Engineering Université de Rennes 1 · 2015 – 2016
- Bachelor's degree, Computer Science Universidad de los Andes, Bogotá · 2007 – 2012
Languages
- Spanish · C2
- English · C1
- French · C1
This site is written in all three.
Beyond data
I'm a tenor and sing whenever I can, I train CrossFit, and I'm endlessly curious about nature, from rivers and forests to the deep ocean.