Data Engineer · PySpark · Databricks · AWS
Hi, I'm Cato. I build data pipelines that turn messy sources into tables people trust.
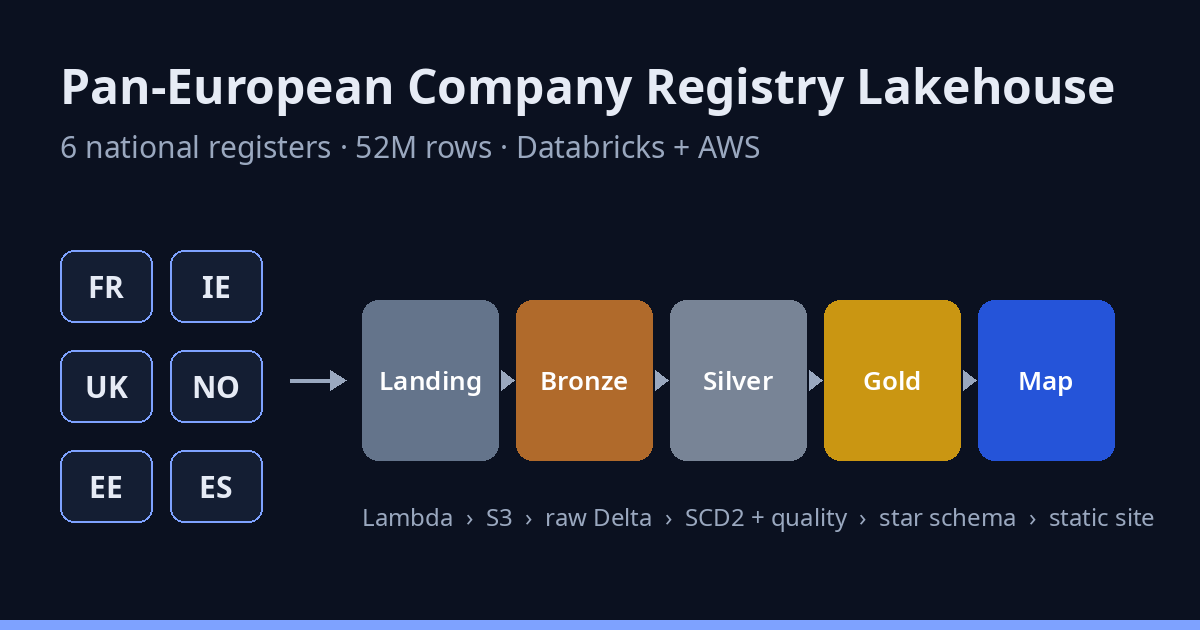
Data engineer with 6+ years of experience building data integration pipelines for finance, insurance, mobility and marketing, from Spark on Hadoop to Azure Data Factory and BigQuery. My latest project is a pan-European company-registry lakehouse on Databricks and AWS: it keeps 52 million register rows up to date every month, and its results are live on this site.
Open to data engineering roles: full-time or contract, remote or on-site in Europe.
Experience with
- Corum L'Épargne
- RiverBank
- Epsilon France (Publicis Groupe)
- Mobilize Financial Services
- PMU
- Allianz France